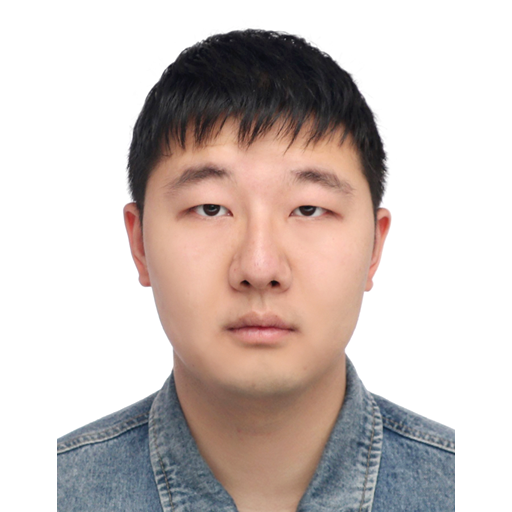
I am a Researcher at Tencent HY, working on speech generation. I received my Ph.D. in Computer Science from Northwestern Polytechnical University (NPU), where I was a member of the Audio, Speech and Language Processing Group (ASLP@NPU), School of Computer Science, supervised by Prof. Lei Xie.
My research interest includes speech synthesis, song generation and speech RL. I have published more than 50 papers at the top international speech conferences and journal.
🔍 Research Area
Speech Processing: Text-to-Speech, Voice Conversion, Speech RL
Music Generation: Song Generation & Evaluation
💻 Experience
- 2026.04 - Present, Hunyuan Tencent - Researcher
- 2025.09 - 2026.02, Seed/Speech ByteDance - Research Intern
- 2025.06 - 2025.09, Data/Douyin ByteDance - Research Intern
- 2024.03 - 2025.02, Nanyang Technological University - Visiting Researcher (supervised by Prof. Eng-Siong Chng)
- 2022.12 - 2024.02, Everest Team Ximalaya - Research Intern
📝 Publications
2025:
- IEEE TASLP FPO: Fine-Grained Preference Optimization Improves Zero-Shot Text-to-Speech. J Yao, Y Yang, Y Pan, Y Feng, Z Ning, J Ye, H Zhou, L Xie. [PDF] [DemoPage]
-
ICLR 2025 GenSE: Generative Speech Enhancement via Language Models using Hierarchical Modeling. J Yao, H Liu, C Chen, Y Hu, ES Chng, L Xie. [PDF] [DemoPage] [Code]
-
AAAI 2025 StableVC: Style Controllable Zero-Shot Voice Conversion with Conditional Flow Matching. J Yao, Y Yang, Y Pan, Z Ning, J Ye, H Zhou, L Xie. [PDF] [DemoPage]
-
IEEE TASLP MUSA: Multi-lingual speaker anonymization via serial disentanglement. J Yao, Q Wang, P Guo, Z Ning, Y Yang, Y Pan, L Xie. [PDF] [DemoPage]
-
ACL 2025 Takin-vc: Zero-shot voice conversion via jointly hybrid content and memory-augmented context-aware timbre modeling. Y Yang, Y Pan, J Yao, X Zhang, J Ye, H Zhou, L Xie, L Ma, J Zhao. [PDF] [DemoPage]
-
AAAI 2025 Drop the beat! Freestyler for Accompaniment Conditioned Rapping Voice Generation. Z Ning, S Wang, Y Jiang, J Yao, L He, S Pan, J Ding, L Xie. [PDF] [DemoPage] [Code]
-
INTERSPEECH 2025 EASY: Emotion-aware Speaker Anonymization via Factorized Distillation. J Yao, H Liu, ES Chng, L Xie. [PDF]
-
arXiv 2025 SongEval: A Benchmark Dataset for Song Aesthetics Evaluation. J Yao, G Ma, H Xue, H Chen, C Hao, Y Jiang, H Liu, R Yuan, J Xu, W Xue, H Liu, L Xie. [PDF] [Code]
- ICASSP 2025 DiffAttack: Diffusion-based Timbre-reserved Adversarial Attack in Speaker Identification. Q Wang, J Yao, Z Sun, P Guo, L Xie, JHL Hansen. [PDF]
2024:
-
IEEE TASLP Distinctive and Natural Speaker Anonymization via Singular Value Transformation-Assisted Matrix. J Yao, Y Lei, Q Wang, P Guo, Z Ning, L Xie. [PDF]
-
ICASSP 2024 PromptVC: Flexible stylistic voice conversion in latent space driven by natural language prompts. J Yao, Y Yang, Y Lei, Z Ning, Y Hu, Y Pan, J Yin, H Zhou, H Lu, L Xie. [PDF] [DemoPage]
-
ICASSP 2024 Dualvc 2: Dynamic masked convolution for unified streaming and non-streaming voice conversion. Z Ning, Y Jiang, P Zhu, S Wang, J Yao, L Xie, M Bi. [PDF] [DemoPage]
-
ICASSP 2024 GEmo-CLAP: Gender-Attribute-Enhanced Contrastive Language-Audio Pretraining for Accurate Speech Emotion Recognition. Y Pan, Y Hu, Y Yang, W Fei, J Yao, H Lu, L Ma, J Zhao. [PDF]
-
INTERSPEECH 2024 DualVC 3: Leveraging Language Model Generated Pseudo Context for End-to-end Low Latency Streaming Voice Conversion. Z Ning, S Wang, P Zhu, Z Wang, J Yao, L Xie, M Bi. [PDF] [DemoPage]
-
VPC 2024 NPU-NTU System for Voice Privacy 2024 Challenge. J Yao, N Kuzmin, Q Wang, P Guo, Z Ning, D Guo, KA Lee, ES Chng, L Xie. [PDF]
-
VPC 2024 NTU-NPU System for Voice Privacy 2024 Challenge. N Kuzmin, HT Luong, J Yao, L Xie, KA Lee, ES Chng. [PDF]
-
ISCSLP 2024 The ISCSLP 2024 Conversational Voice Clone (CoVoC) Challenge: Tasks, Results and Findings. K Xia, D Guo, J Yao, L Xue, H Li, S Wang, Z Guo, L Xie, Q Zhang, L Luo, M Dong, P Sun. [PDF]
-
ISCSLP 2024 The NPU-HWC System for the ISCSLP 2024 Inspirational and Convincing Audio Generation Challenge. D Guo, J Yao, X Zhu, K Xia, Z Guo, Z Zhang, Y Wang, J Liu, L Xie. [PDF]
-
Report Takin: A Cohort of Superior Quality Zero-shot Speech Generation Models. [PDF]
2023:
-
ICASSP 2023 Preserving background sound in noise-robust voice conversion via multi-task learning. J Yao, Y Lei, Q Wang, P Guo, Z Ning, L Xie, H Li, J Liu, D Xie. [PDF] [DemoPage]
-
ICASSP 2023 Distinguishable speaker anonymization based on formant and fundamental frequency scaling. J Yao, Q Wang, Y Lei, P Guo, L Xie, N Wang, J Liu. [PDF]
-
ICASSP 2023 Expressive-vc: Highly expressive voice conversion with attention fusion of bottleneck and perturbation features. Z Ning, Q Xie, P Zhu, Z Wang, L Xue, J Yao, L Xie, M Bi. [PDF] [DemoPage]
-
IEEE TASLP Timbre-reserved Adversarial Attack in Speaker Identification. Q Wang, J Yao, L Zhang, P Guo, L Xie. [PDF]
-
ASRU 2023 Salt: Distinguishable Speaker Anonymization Through Latent Space Transformation. Y Lv, J Yao, P Chen, H Zhou, H Lu, L Xie. [PDF] [Code]
-
INTERSPEECH 2023 Pseudo-Siamese Network based Timbre-reserved Black-box Adversarial Attack in Speaker Identification. Q Wang, J Yao, Z Wang, P Guo, L Xie. [PDF]
-
INTERSPEECH 2023 Dualvc: Dual-mode voice conversion using intra-model knowledge distillation and hybrid predictive coding. Z Ning, Y Jiang, P Zhu, J Yao, S Wang, L Xie, M Bi. [PDF] [DemoPage]
-
AAAI 2023 UniSyn: an end-to-end unified model for text-to-speech and singing voice synthesis. Y Lei, S Yang, X Wang, Q Xie, J Yao, L Xie, D Su. [PDF] [DemoPage]
-
DADA@IJCAI 2023 The NPU-ASLP System for Deepfake Algorithm Recognition in ADD 2023 Challenge. Z Wang, Q Wang, J Yao, L Xie. [PDF]
-
SMAC 2023 Exploring the power of cross-contextual large language model in mimic emotion prediction. G Yi, Y Yang, Y Pan, Y Cao, J Yao, X Lv, C Fan, Z Lv, J Tao, S Liang, H Lu. [PDF]
2022:
- VPC 2022 NWPU-ASLP system for the voiceprivacy 2022 challenge. J Yao, Q Wang, L Zhang, P Guo, Y Liang, L Xie. [PDF]
🎖 Honors and Awards
- 2023.06 The 4th place winner for the Deepfake Algorithm Recognition task in the Audio Deepfake Detection (ADD) Challenge @ IJCAI Workshop, 2023.
- 2022.09 The 1th place winner in the VoicePrivacy Challenge (VPC) 2022 @ INTERSPEECH Workshop, 2024
💬 Service
- Reviewer
- IEEE TASLP
- IEEE SPL
- Speech Communication
- ICASSP 2024, 2025
- INTERSPEECH 2024, 2025
- ACM MM 2024, 2025
- ICLR 2025
- IJCNN 2025
- Organizer
- Conversational Voice Clone Challenge (CoVoC) @ ISCSLP 2024
Thanks for the template of acad-homepage.github.io